One gateway for every LLM call
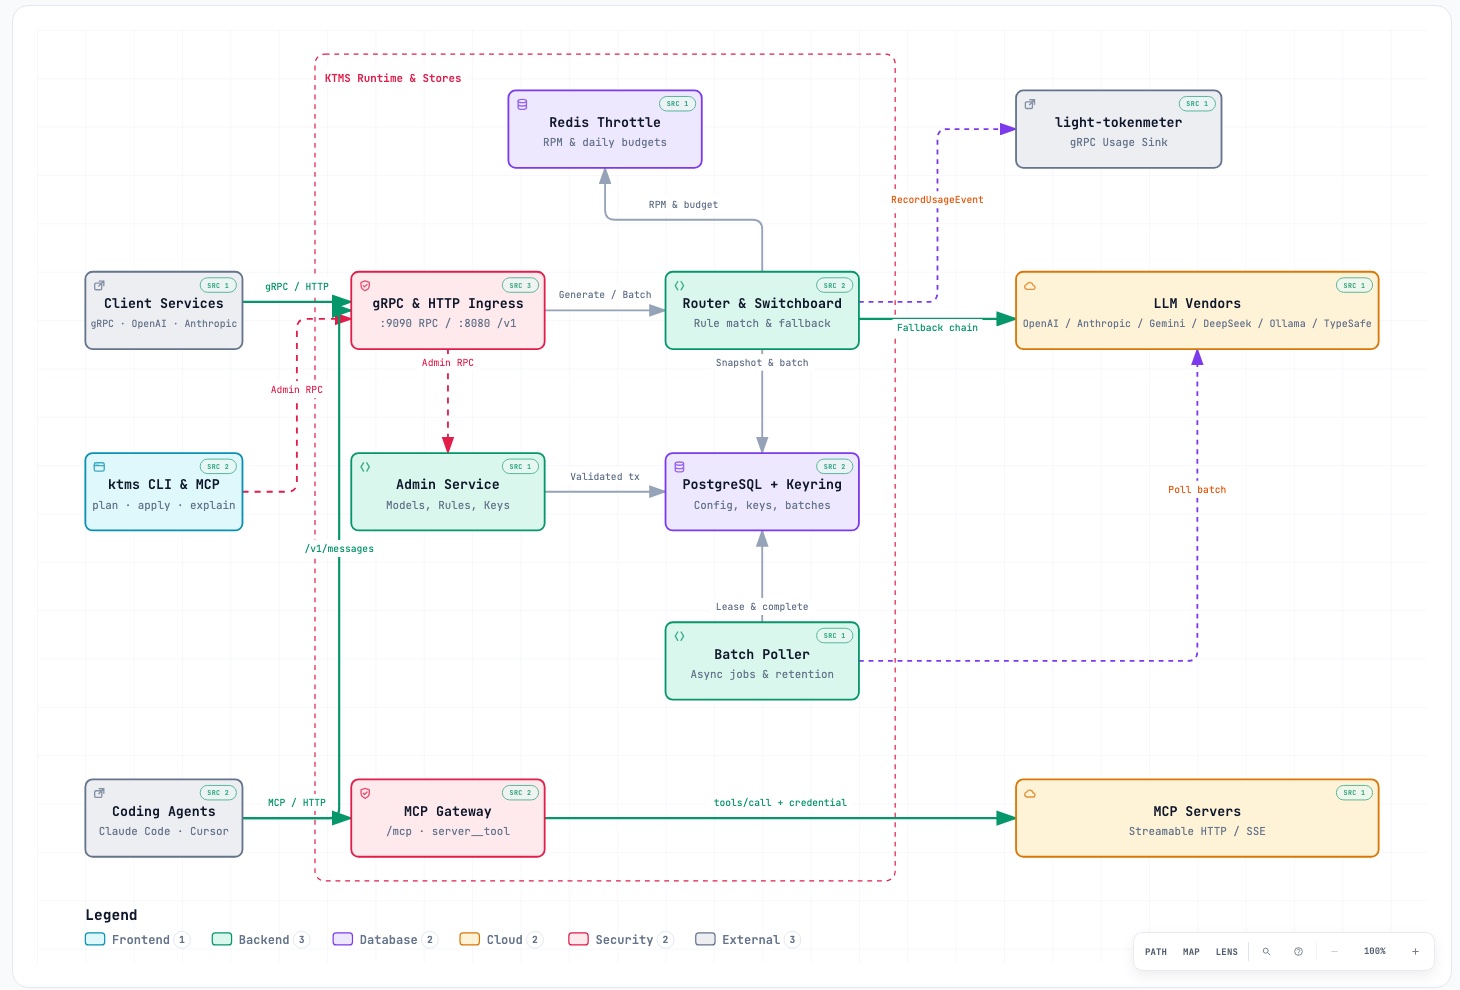
Keystone (KTMS) is an open-source, self-hosted LLM gateway. Services ask for an effort level instead of a model; Keystone holds the vendor keys, picks the model chain, falls back when a vendor is down, and enforces rate and spend limits.
It started as the LLM proxy behind snappyloop and became a standalone product, built on the same AI-native delivery model: a single Go binary with gRPC, OpenAI- and Anthropic-compatible APIs and an MCP gateway, about 7 MiB of idle memory and under a millisecond of added latency.
The operational problems of running LLMs in production are handled in the gateway, not in every service: hard spend caps per key, end user and team, reserved atomically before each call; per-vendor circuit breakers and fallback chains; local inference nodes on idle Macs and GPU boxes with cloud fallback; and signed releases with an SBOM and SLSA provenance.
Around it: light-tokenmeter for usage reporting, the ktms-admin web console, and a Claude Code plugin whose skills assess, deploy and integrate the gateway — with CI that fails when a skill names a command the release does not have.